

 Read Client Stories




 Alex Kugell
 Key Takeaways
- Treat replication as availability. A second copy will faithfully reproduce an accidental deletion, so decide how much data loss and downtime the business can tolerate before choosing a recovery arrangement.
- 99.99 percent uptime allows a few minutes of downtime a month, while 99.999 percent allows seconds, and the two numbers point to very different architectures.
- Expect stale payment statuses across regions. Asynchronous replication means a second region can show an older status after a failover, so agree upfront which decisions need current records.
- Make retries idempotent. Most duplicate charges come from a client retrying, not from the acquirer.
- Spread acquirer risk with dynamic routing, so one partner's rising latency turns into a reroute rather than an outage.
- Count security work as uptime work. A breach, or missing KYC and AML controls, can take payment flows offline as effectively as a failed node.
When a payment system fails, people notice immediately.
A small hiccup that stops a transaction for even a few seconds may look harmless on paper, but in the moment, it creates real anxiety for the user who just wants their card to work.
For a business, it often means lost revenue, a support ticket, and a little less customer trust than before. As payment processing grows more complex and increasingly real-time, these small failures tend to add up.
What makes this tricky is that a modern payment platform sits on top of a mesh of critical systems. You rely on networks, issuers, acquirers, payment gateways, and third parties.
Any one of them can slow down or create a single point of failure. Without high availability baked into the architecture, you end up reacting to problems instead of preventing them.
The encouraging part is that you can design a highly available and genuinely resilient processing system when you place reliability, uptime, and scalability at the center of your choices.
Our fintech developers here at Trio can help you do that.
But before you jump into hiring expert payment developers, let’s make sure you understand the intricacies of a high-availability, scalable payment system.
Why High Availability Matters in Payment Processing
A reliable payment system is more than an engineering preference. It is the quiet backbone that keeps e-commerce, subscription billing, and in-person transactions running without interruption.
When high availability drops, downtime becomes real money lost.
Customer Trust and Revenue Protection
The moment a transaction stalls or fails, the customer experience suffers. People have very little patience during checkout, and even less when they are unsure if their card was charged.
The harm spreads wider than the initial incident, since the customer may think twice about returning.
High uptime is not simply a performance goal. It is a financial one.
Regulatory Expectations and Market Pressure
Financial institutions, payment gateways, and modern payment services operate under strict expectations for uptime and data protection.
Regulations around PCI DSS compliance, KYC, and AML tend to raise the baseline.
At the same time, global payment processors have pushed expectations higher simply by operating at the volume they do, with downtime measured in seconds rather than hours.
For any business handling payment transactions at scale, the bar is now much higher than it used to be.
Understanding High Availability in a Payment System
Most teams hear the phrase high availability and picture a system that never breaks. In reality, the goal is slightly different.
A highly available processing system is built so the user rarely notices failures, even when components break behind the scenes.
Related Reading: Payment Facilitation (PayFac) Explained
What High Availability Means
High availability is usually defined by an availability SLA such as 99.9, 99.99, or 99.999 percent uptime.
These might sound abstract at first, but the numbers translate to very real expectations.
An SLA of 99.99 percent lets you have a few minutes of downtime per month. Once you reach the mission-critical threshold of 99.999 percent, the allowed interruptions shrink to seconds.
Visa, for comparison, has described its own network's standard as "six nines": 99.9999 percent availability, or under a second of downtime per day across the whole network.
Absolute perfection is unrealistic, but the idea is to remain operational and accessible even when parts of the system become unreliable.
Core Components of High Availability
Reliable payment processing depends on layers of protection.
Failover mechanisms shift traffic away from struggling nodes.
Redundancy in storage, compute, and network paths reduces dependence on individual components, but does not guarantee that payment records cannot be lost.
Replication can also copy an accidental deletion. Agree how much data loss and downtime the business can tolerate, then choose backup and recovery arrangements and test whether they meet those requirements.
Load balancing across multiple servers limits vulnerability to peak loads.
Taken together, these patterns reduce the chance of a disruption reaching the customer.
Architectural Foundations for Resilient Payment Systems
A payment processing system needs an architecture capable of handling millions of transactions under unpredictable conditions.
Designing for high availability early avoids expensive fixes later.
Transaction Processing at Scale
When payment transactions spike or an acquirer slows down, problems spread quickly. High-volume transactions put pressure on networking, validation workflows, and settlement paths. It may also introduce odd consistency problems.
For example, you might see a payment authorization succeed, but the clearing step gets delayed due to data replication issues.
These situations are common in extremely high-traffic systems and deserve attention before you grow.
Scaling Approaches for Reliability
Horizontal scaling is often the simplest path forward because it spreads your workload across multiple servers.
Active systems are common in payment gateways because they let you process transactions simultaneously across regions.
Event-driven architecture helps isolate workflows so that failures in one part of the payment platform do not ripple into others.
Each of these choices comes with tradeoffs, of course, but they tend to push reliability in the right direction.
Load Balancing and Traffic Management
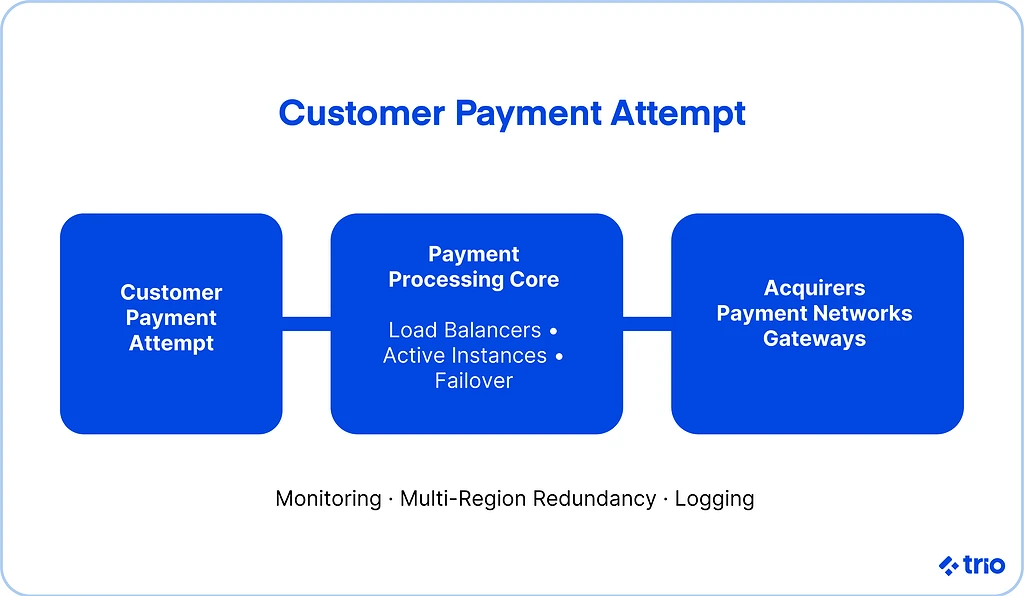
A healthy processing system adjusts at the edge. Load balancing distributes traffic across available instances and avoids routing users into a bottleneck.
Health checks give you early signals when a gateway or region begins to degrade. It may look like a small operational detail, yet it often saves you from a major outage.
Redundancy and Multi-Region Deployment
Redundancy gives you breathing room. With N+1 capacity, your system can keep running even if a node fails.
Multi-region deployment can help keep a payment service available during a regional outage, but copying data between regions does not automatically keep every copy current.
With asynchronous replication, updates arrive later, so another region may temporarily show an older payment status. Waiting for updates to reach multiple copies can improve consistency, but adds latency.
Before choosing a design, agree which payment decisions require up-to-date records, where temporary delays are acceptable, and who owns resolving uncertain statuses after a failure.
Still, it is one of the more reliable ways to avoid catastrophic downtime.
Continuous Availability Patterns
When you aim to process payments reliably, small design patterns become powerful tools.
Circuit breakers can cut off a failing downstream service before it drags everything else down. Queues smooth uneven workloads. Retry logic helps recover from transient network issues.
None of these solves downtime alone, but they create a safer baseline when combined.
Routing and API Layer Reliability
Your routing logic and API design often determine how well your system handles failures from external payment services.
These layers may appear simple, but they carry a large share of responsibility for high availability.
Smart Routing Techniques for Payment Transactions
A modern payment gateway often talks to multiple acquirers and services.
Dynamic routing lets your system redirect transactions when a provider’s latency rises or its workflow becomes unreliable.
Multi-acquirer setups help you avoid depending too heavily on one partner.
Smart failover logic fills in the gaps when things go wrong.
API Design for High Availability
An API-driven payment platform benefits from stability more than anything else.
Idempotency prevents duplicate charges when clients retry a request.
Versioning supports long-lived integrations without breaking them during updates. Timeouts and retries help balance customer experience and system protection.
These might seem like small API details, but they often make the difference between smooth payments and visible failures.
Operational Excellence and Reliability Management
Architecture alone cannot guarantee uninterrupted service.
A payment processing system needs an operational culture that treats reliability as an ongoing practice.
Real-Time Observability and Monitoring
Real-time observability gives you visibility into latency, workload patterns, and odd behaviors that may suggest upcoming system failures.
Traces help you understand exactly where a transaction slows down. Logs provide context when workflows misbehave.
When you operate a mission-critical processing solution, early signals are priceless.
Applying SRE Principles to Payments
Site Reliability Engineering shapes how many modern payment platforms work.
Error budgets help you balance shipping features against creating risk. Runbooks guide teams under pressure. Post-incident reviews help you reduce the chance of repeating the same outage.
The practice is not perfect, but even lightweight adoption helps maintain high uptime.
Security and Compliance as Stability Foundations
PCI DSS compliance, firewalls, and careful handling of sensitive data all support long-term reliability. Breaches create downtime.
Weak authentication or missing KYC and AML controls can slow payment workflows. In the context of payment transactions, security and uptime tend to reinforce each other rather than compete.
Case Studies: How Leading Platforms Achieve High Availability
Looking at the habits of major payment providers offers a clearer picture of what works in the real world.
Patterns From Major Payment Processors
Companies such as Visa, Adyen, and Stripe rely on multi-region deployments, aggressive health monitoring, and traffic shaping techniques that constantly adjust.
They often build custom routing and orchestration layers to handle changes across multiple regions.
Lessons From Failures and Outages
Outages happen to nearly everyone, even highly experienced teams.
Common issues include routing mistakes, data replication delays, or unexpected surges from e-commerce partners.
The teams that recover quickly tend to focus on transparency, careful analysis, and long-term fixes.
Future Trends in High Availability Payment Architecture
Payment processing is changing quickly on several fronts.
Some trends may seem experimental today, but are likely to influence the next generation of payment solutions.
AI-Driven Routing and Predictive Failover
AI has already become part of many routing workflows. It appears especially promising for identifying patterns that signal an upcoming slowdown.
With enough data, a system may proactively route payments away from deteriorating providers.
Autonomous Payment Infrastructure
Some teams are testing systems that adjust capacity and routing on their own.
While still early, this direction could reduce manual intervention during high-volume transactions.
Cross-Border Real-Time Payments
As ISO 20022 adoption spreads and real-time networks grow, more transactions will rely on consistent latency across multiple regions.
Keeping these rails reliable without high operational complexity is becoming a larger challenge.
Blockchain-Based Settlement Networks
Distributed systems and blockchain-based settlement models may offer alternative workflows where data loss is harder to achieve, and transaction settlement becomes more predictable.
Conclusion
A scalable and highly available payment system does not happen accidentally. It is the result of deliberate choices in system architecture, routing, APIs, and day-to-day operations.
When you build for reliability early, you give your business room to grow without interruption. You safeguard customer trust and reduce the risk of painful downtime.
And you help your payment platform process transactions smoothly, regardless of what the underlying networks decide to do on any given day.
To find expert fintech developers who can ensure your systems are built for availability and long-term scalability, get in touch!